
Computer Vision
2D/3D boxes, polygons, segmentation masks, and temporal tracking.
Guideline-calibrated annotation, RLHF, and QA—delivered by dedicated specialist pods.
Your ontology, your platform, our team.
Engagement model Start with a call or message

2D/3D boxes, polygons, segmentation masks, and temporal tracking.
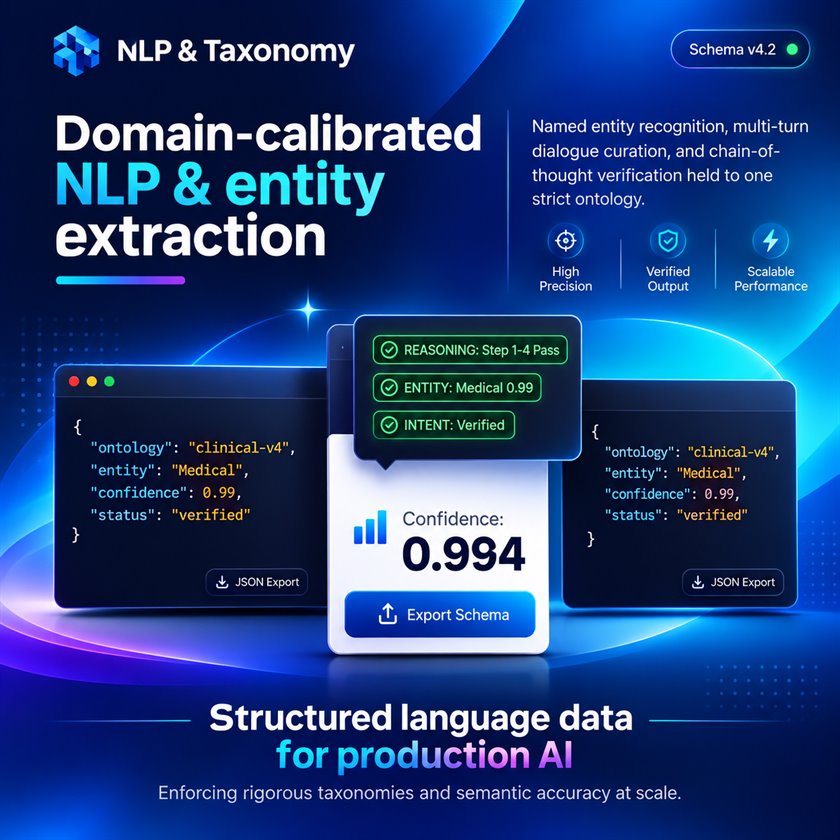
Entity extraction, intent classification, and domain-calibrated text curation.
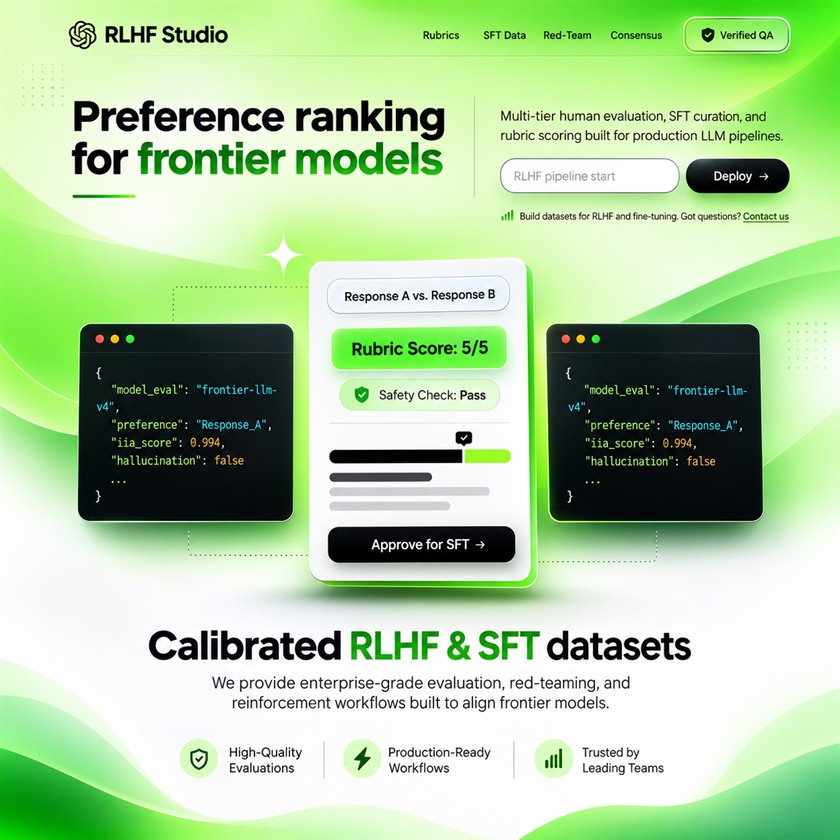
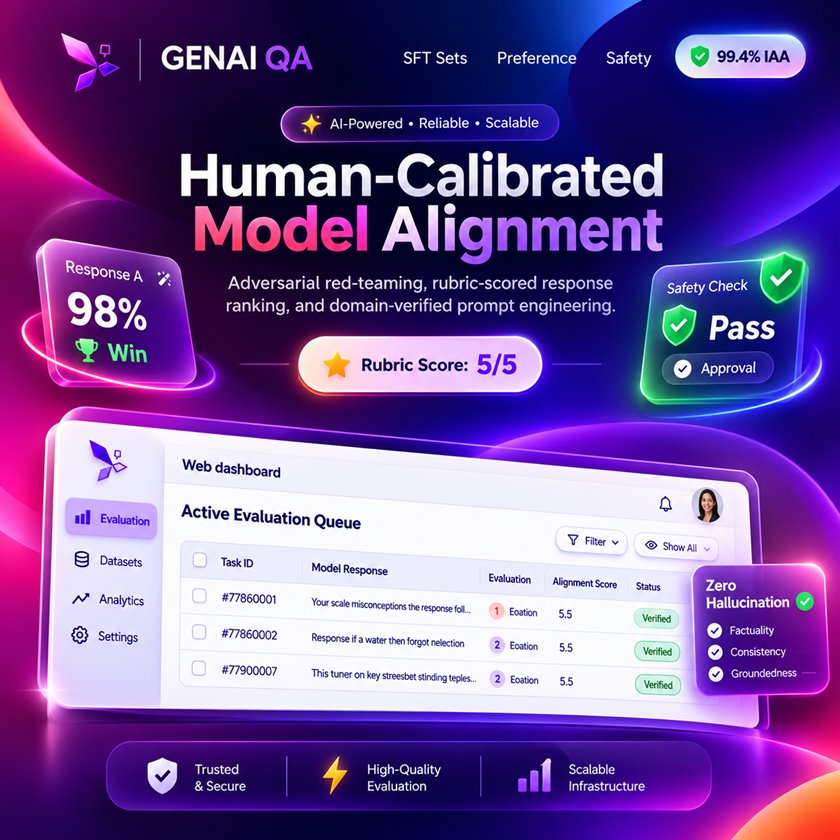
SFT datasets, RLHF preference ranking, red-teaming, and rubric evaluation.


Every engagement begins with a calibrated ontology—and holds to it. Ambiguities are surfaced and resolved, never guessed. A lead specialist or a dedicated 1–5 person pod runs the queue without daily management, and multi-tier QA delivers production-ready ground truth to your pipeline.
Operational standard
Replace fragmented crowdsourcing and high-overhead vendors with a dedicated specialist practice.

Prioritize batches, track velocity, and monitor QA status in one workspace.

Strict adherence to your schema, with documented edge-case escalation logs.

Define your rubric once. Batches move ahead without daily oversight.

Every batch gets a specialist audit and a consensus check before export.

Scale from one lead specialist to a calibrated five-person pod as volume grows.

We work inside your stack: Labelbox, SuperAnnotate, CVAT, V7, or custom tools.
"Ground truth engineered to your ontology, never approximated."
"Dedicated pods that plug into agency and enterprise pipelines."
 Computer Vision & Spatial
Dense polygons, semantic masks, and video tracking
99.4%+ QA Consensus LLM & NLP Alignment
RLHF ranking, SFT curation, and domain NER
Rubric-Verified OutputProduction-grade annotations calibrated for high-stakes models.
Request sample schemas

Engagement model
Direct or agency partner
1–5 calibrated specialists
Dedicated
pod
Crowdsourced
Included


Scale capacity up or pause between model training cycles—your calibrated ontology stays intact.

Align on your schema, sample batch, or partnership via a 15-minute call or async brief.
Calibration batches and active queues typically return within 24 to 48 business hours. Larger datasets and multi-stage RLHF work move on agreed daily throughput, so verified batches keep reaching your pipeline.

We review your schema, edge-case rules, and model objectives, then configure the shared queue. A short calibration batch locks alignment, and production starts without daily oversight.
Work stays with a senior specialist, expanded to a calibrated pod of up to five when volume or domain complexity requires it. Nothing is sent to anonymous crowds. Every batch passes an independent QA review before export.
Yes. Alongside direct work with machine learning teams, the practice collaborates with AI consultancies, agencies, corporate R&D groups, and independent specialists—as an embedded unit, an overflow pod, or a longer delivery partner.
Pause when a dataset is complete and your team is evaluating checkpoints. Resume when the next cycle is ready. Guidelines, tooling, and the calibrated team stay in place.
Large sets are split into milestone batches. The pod scales from one specialist to five annotators and reviewers, with verified partitions delivered every 24 to 48 hours until the corpus is complete.
We work in your stack, including Labelbox, SuperAnnotate, Scale, V7, CVAT, Label Studio, Encord, or an internal tool. Exports include JSON, COCO, YOLO, Pascal VOC, CoNLL, Parquet, or a custom schema, under NDA.
Edge cases are logged and resolved against your rubric, not guessed. Each batch is checked before delivery. If a label misses the specification, we recalibrate and correct it at no additional cost.


